 unbrowse
The web spent 30 years learning how to serve humans.
Now it has to serve machines.
The current plan seems to be:
Every website builds an API.
Then documentation.
Then an SDK.
Then OAuth.
Then an MCP server.
Then every agent integrates it.
Then, eventually, agents can use the web.
There is one problem.
Agents aren’t going to wait.
The integration model doesn’t scale
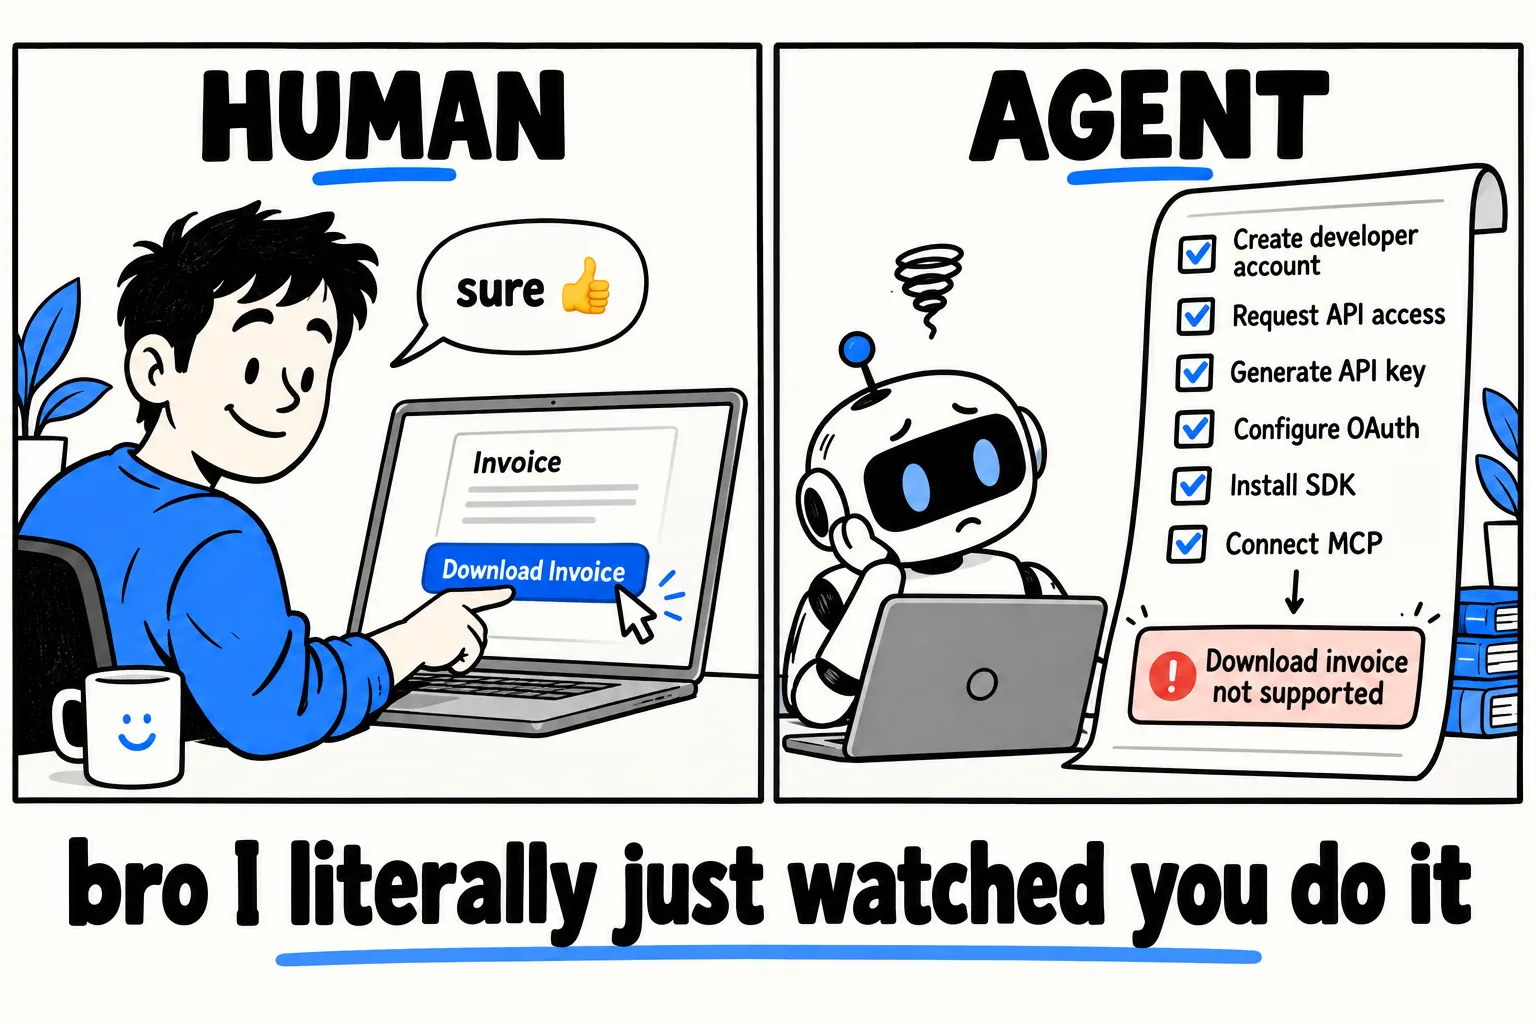
Are we really expecting every website to separately decide how agents should interact with it?
Product chooses which capabilities agents get.
Engineering builds the API.
Someone documents it.
Someone maintains the SDK.
Someone builds the MCP server.
Someone configures authentication.
Then the agent integrates it.
Repeat for the entire internet.
Every company. Every product. Every feature someone might want an agent to use.
And when the feature changes, work your way back through the layers.
This is backwards.
We’re trying to make the entire web integrate with agents.
Agents are increasingly capable of integrating with the web themselves.
And the interface they need often already exists.
Your website already has an API
Open a modern web app.
Search for something. Change a setting. Load your transactions. Download an invoice. Add something to your cart.
Watch the network tab.
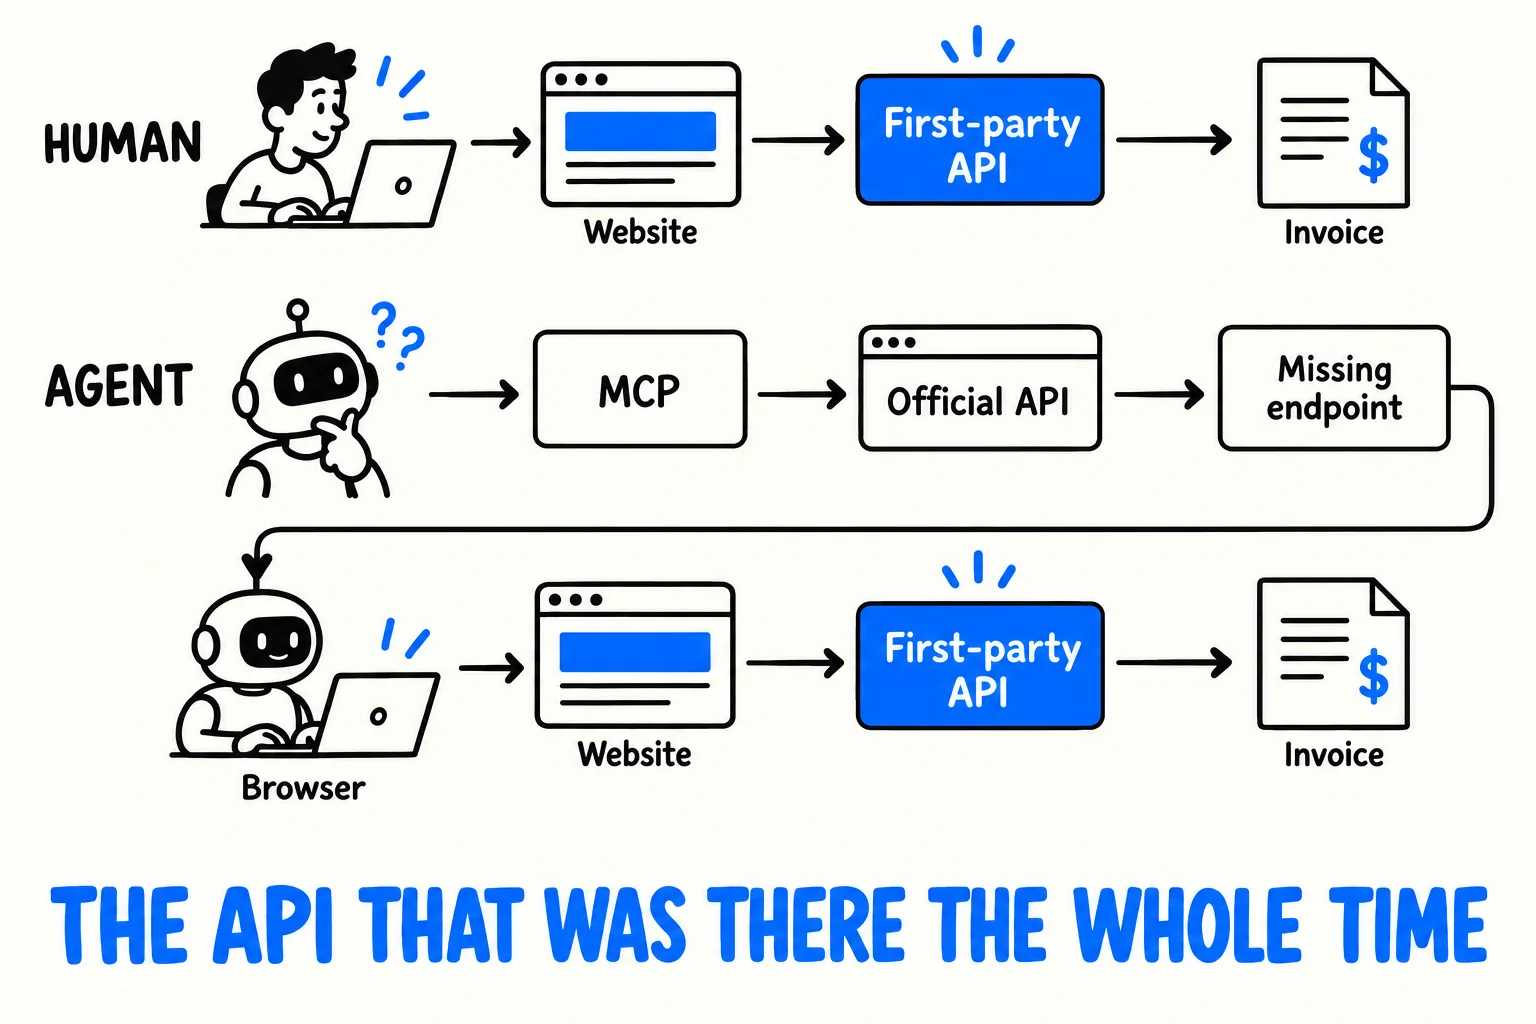
In many of these apps, your browser is making structured requests to the website’s own first-party APIs.
The button isn’t the capability.
The HTTP request underneath it is.
The website already has a machine interface because the website itself is a machine using it.
Then an agent arrives and suddenly we pretend this interface doesn’t exist.
The browser can download the invoice today.
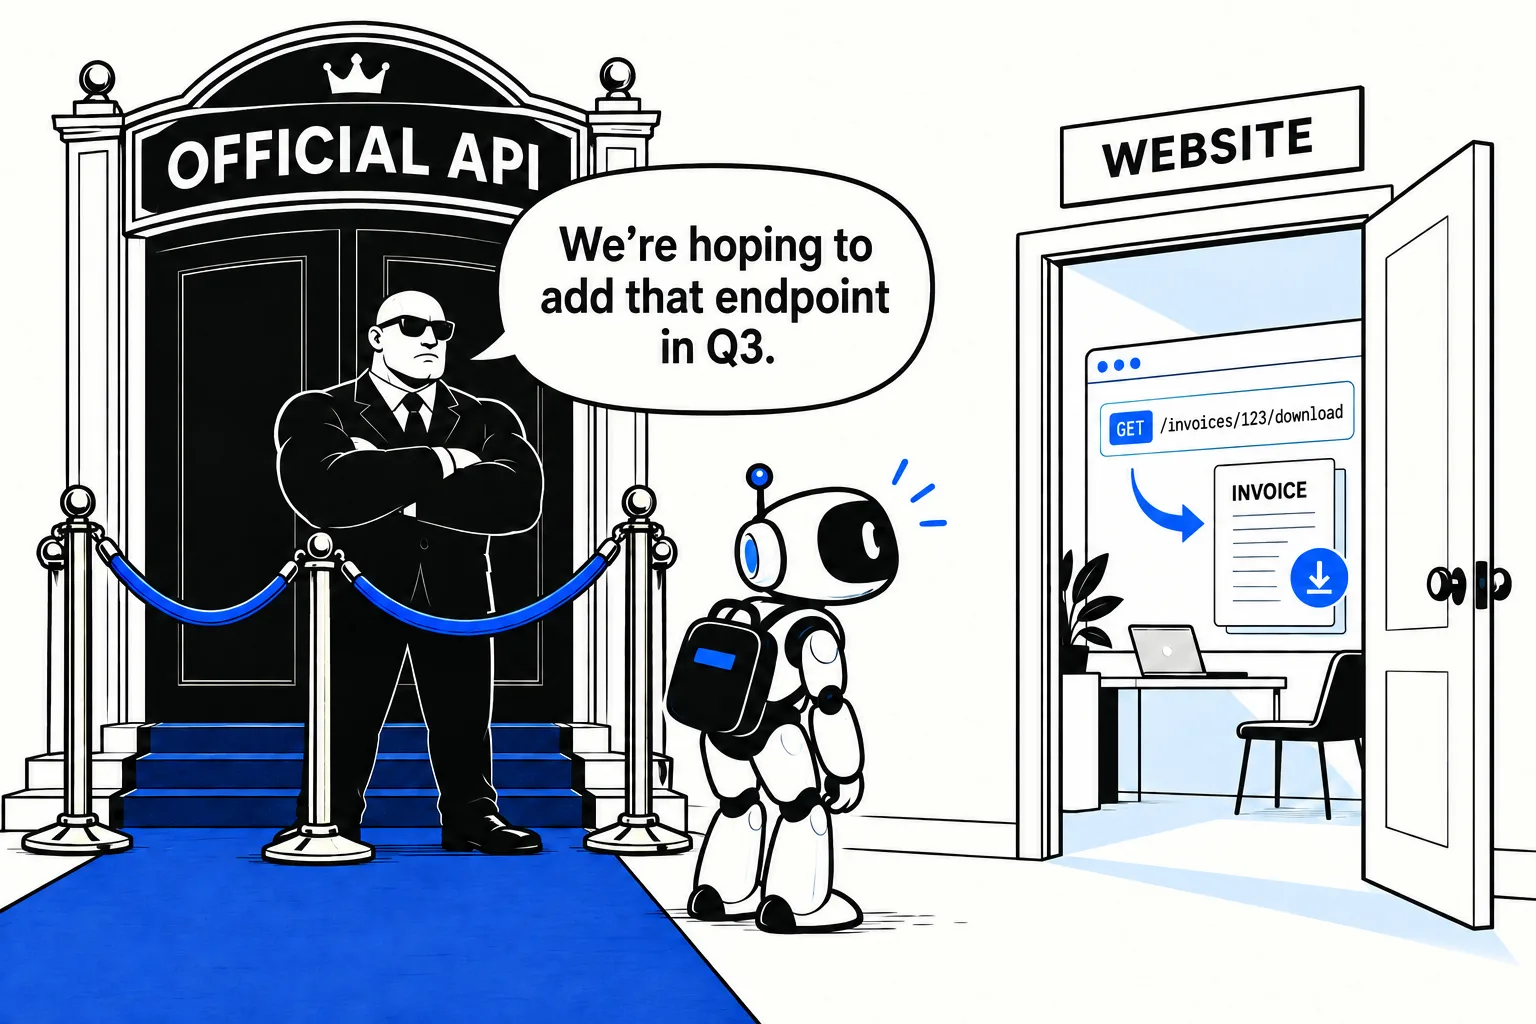
The agent gets told to wait for the API roadmap.
“We don’t expose that capability through our API yet.”
I just watched the website do it.
“Yes, that’s the first-party API.”
Oh, sorry. I didn’t realize the request hadn’t been introduced to society.
Does it need a little sash? Do we take it to a developer conference and formally announce that computers may now send it JSON?
The operation exists. The account can perform it. The service’s own client does it all day.
Then a second client comes along and the same capability needs another launch date.
The browser gets the product.
The agent gets the product’s interpretation of the product.
A wrapper around a wrapper around a wrapper
Look at the stack we keep assembling.
Build an API for your website. The browser talks to it. It works.
Now build an official API over the capabilities you already built, with its own credentials and a separate list of things it supports.
Now build an SDK around that API, so developers don’t have to write the requests themselves.
Now put an MCP server in front of it, so an agent can use a tool that calls the client that calls the official interface to the capability your browser was already using.
Now package the server as a connector.
Now give the connector an onboarding flow.
Now ask the user to connect their account.
Connect to what? The browser is talking to it right now.
Here is the endpoint.
Here is the schema describing the endpoint.
Here is the tool describing the schema describing the endpoint.
Here is the connector that exposes the tool describing the schema describing the endpoint.
We are four explanations deep and nobody has downloaded anything.
You have taken a working HTTP request and given it a management structure.
Apparently each layer abstracts away everything except its own setup.
“First, create a developer account.”
I wanted a receipt. When did I become a developer?
“Generate an API key.”
Is that my password?
“No, this is a different credential.”
Of course it is. The password only works on the website, where the thing I want is currently available.
“Now configure a service account.”
I thought I was paying you for the service.
The assistant was supposed to take work off my hands. It has hired me as its integration engineer.
And after all that, perhaps the official API lets you list invoices but not download them.
The SDK cannot download them either.
Neither can the MCP server.
Neither can the connector.
Wrap it again. Still missing.
Congratulations. You’ve standardized the disappointment.
Permissionless ≠ unauthorized
“Permissionless” does not mean bypassing authentication, accessing someone else’s data or ignoring the permissions of the underlying service.
It means using a website on behalf of a user shouldn’t require a separate developer relationship with that website.
Think about hiring an employee.
You don’t email every SaaS company your business uses and ask:
Hi, have you implemented Employee Protocol yet?
You give the employee appropriate access.
Their own account. A workspace invitation. Delegated access. Whatever makes sense.
You explain the job and its limits.
The service’s existing permissions continue to apply.
Why should agents be fundamentally different?
Some authentication needs browser state or a human approval. Fine. Handle that.
But why does every engineering requirement have to come back to the user wearing a setup wizard?
Remove integration permission, not user permission.
Sites don’t integrate with agents. Agents integrate with sites.
This is the inversion.
Today:
Website → builds integration → Agent → User gets capability
Tomorrow:
User wants something → Agent learns website → capability works
The site’s own frontend already demonstrates how its product works.
Search. Filter. Create. Update. Purchase. Download.
Every interaction can teach the machine something.
The frontend is, in effect, an executable specification: a working demonstration of the requests, inputs and state the operation needs.
“But the agent needs to know how to use the API.”
You sold me an agent that can write software. Let it write the client.
Why does the API have to learn a new protocol before the agent can learn an old one?
The website doesn’t need to integrate with the agent.
The agent can integrate with the website.
The browser is the bootstrap
Browser agents were an important breakthrough.
The browser is the web’s broadest compatibility layer. It gives agents a way to open, understand and operate software that was never designed for them.
But the browser doesn’t have to be the final abstraction.
Imagine an agent needs an invoice. The official integration doesn’t support the download.
“I’ll open the website.”
Oh, we’re back here.
We did the developer account, the API key and the connector so the agent could announce that it needs the website. The one with the feature our account could already use.
Now it opens the browser.
Navigates to the website.
Loads the app.
Runs the JavaScript.
Renders the dashboard.
Inspects the interface.
Finds the billing menu.
Clicks it.
Waits for the billing page.
Inspects the interface again.
Finds the invoice.
Finds the download button.
Clicks it.
The frontend makes a request. In our example:
GET /invoices/123/download
The invoice arrives.
Great.
Tomorrow the agent needs another invoice.
Open the browser. Load the app. Run the JavaScript. Find the menu. Render the page. Inspect the interface. Find the invoice. Find the button. Click it.
Again.
Compute to run the interface. Tokens to operate it. All to reach the operation we already watched it perform yesterday.
The API has a wrapper that has a wrapper that eventually gives up and opens Chrome.
Should this really be the permanent architecture?
Once we’ve learned the operation and verified that it can be reused, we can go from:
intent → browser → DOM → click → frontend → API
to:
intent → API
The browser doesn’t disappear.
Use it for authentication.
Use it for discovery.
Use it when browser state matters.
Use it when something changes.
Use it as fallback.
But don’t make the machine cosplay as a human forever just because that’s how it discovered the operation.
The billing animation does not need to finish for the concept of an invoice to exist.
For an operation that can be learned and replayed, the browser is the bootstrap, not the runtime.
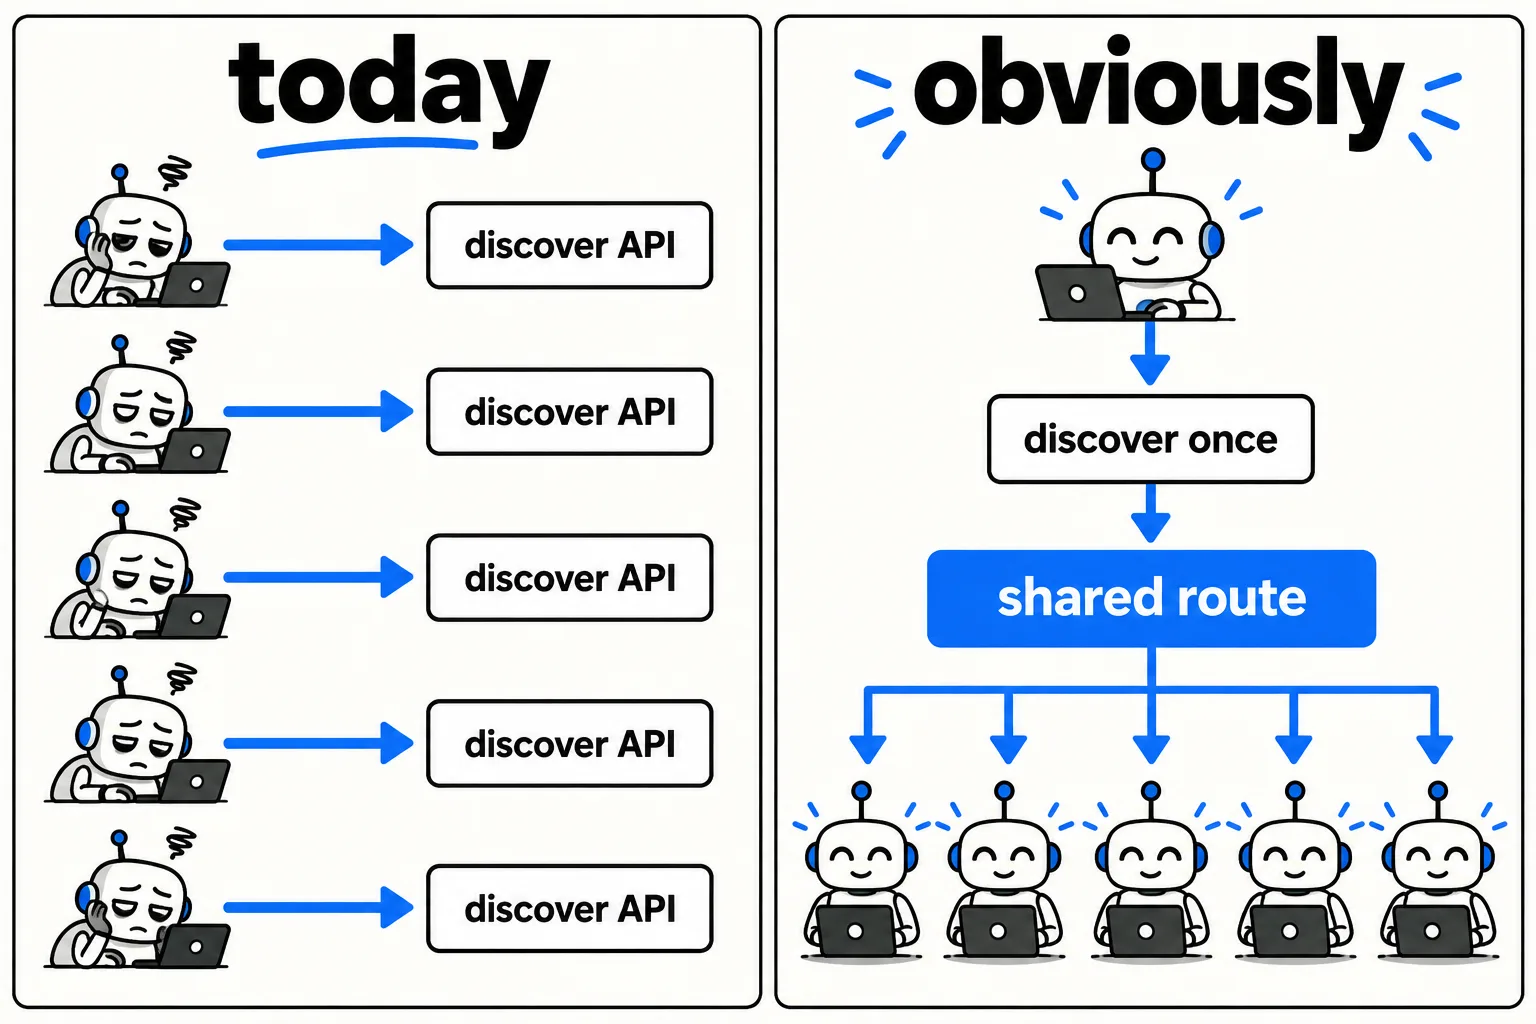
Discover once. Reuse everywhere.
There’s an even bigger problem.
Agent #1 encounters a website. It figures out how it works.
Agent #2 arrives tomorrow. It figures out how it works.
Agent #3 does the same thing.
And Agent #4.
And Agent #5.
Same website.
Same menus.
Same requests.
A fresh discovery every time.
Imagine millions of intelligent machines independently reverse-engineering the same interfaces.
Why?
Search engines made discovery reusable for people. The thousandth person searching for something didn’t have to retrace the first person’s path through the web.
Agents need the same thing for capabilities.
The first agent might have to discover how something works.
The thousandth shouldn’t.
Share the knowledge of how the operation works. Keep each user’s credentials and private data out of it.
Knowing where the invoice lives does not give you permission to read mine.
Search indexed what the web knows. Agents need an index of what the web can do.
Google maps:
query → page
Agents need:
intent → capability
“Find my latest invoice.”
“Cancel my reservation.”
“Check whether this product is back in stock.”
“Update my address.”
“Pull last month’s analytics.”
“Submit this form.”
These aren’t requests for webpages.
They’re operations.
Humans need interfaces around operations.
Agents increasingly don’t.
For agents, the useful primitive becomes:
intent → route + schema + auth + execution
Pages were the primitive of the human web.
Capabilities can become the primitive of the agentic web.
This doesn’t mean APIs or MCP are useless
Quite the opposite.
If you operate a service, make yourself easy for agents to use.
Build stable APIs. Provide good authentication. Expose structured data. Document your capabilities. Build MCP servers when they make things easier.
Official APIs can provide stability, documentation and narrower permissions. A first-party interface can change and leave you fixing it.
That is a real tradeoff.
MCP does not require the entire wrapper procession above. Teams choose that architecture. A shared tool contract can be useful. Discovery can be useful. Packaging an ugly workflow can be useful.
Do that work. Show me what disappeared from the user’s plate.
The mistake is believing:
no official integration = no capability
The user is often performing that exact capability on your website right now.
The operation exists.
The account can perform it.
The site’s own client knows how to perform it.
Agents are getting good enough to figure out the rest.
And yes, Unbrowse has machinery too. We expose APIs and MCP tools. We have not defeated abstraction by choosing a shorter name.
If our machinery hands the user another integration project, roast us with the same paragraph.
The test is whether the abstraction removes work.
The agentic web won’t be built one integration at a time
This is what we’re building Unbrowse around.
There is already an enormous machine interface underneath the human web.
First-party APIs power the applications we use every day.
Browsers reveal how those interfaces work.
Agents can learn them.
And what one agent discovers can become reusable infrastructure for the next.
Unbrowse is built around permissionless access to the first-party APIs of the web.
Use official interfaces when they’re available and sufficient.
Discover the underlying interface when they aren’t.
Use the browser when the browser is actually needed.
Verify what can be reused.
Reuse what has already been learned.
Today, Unbrowse can discover capabilities, learn from browser requests and replay verified routes. Its public registry shares eligible read-only, secretless operations; private sessions and writes stay out of that public pool. The documentation explains how to try the loop, and the capability index explains the larger idea.
The ambition is something bigger than browser automation.
It’s a machine-readable map of what the internet can do.
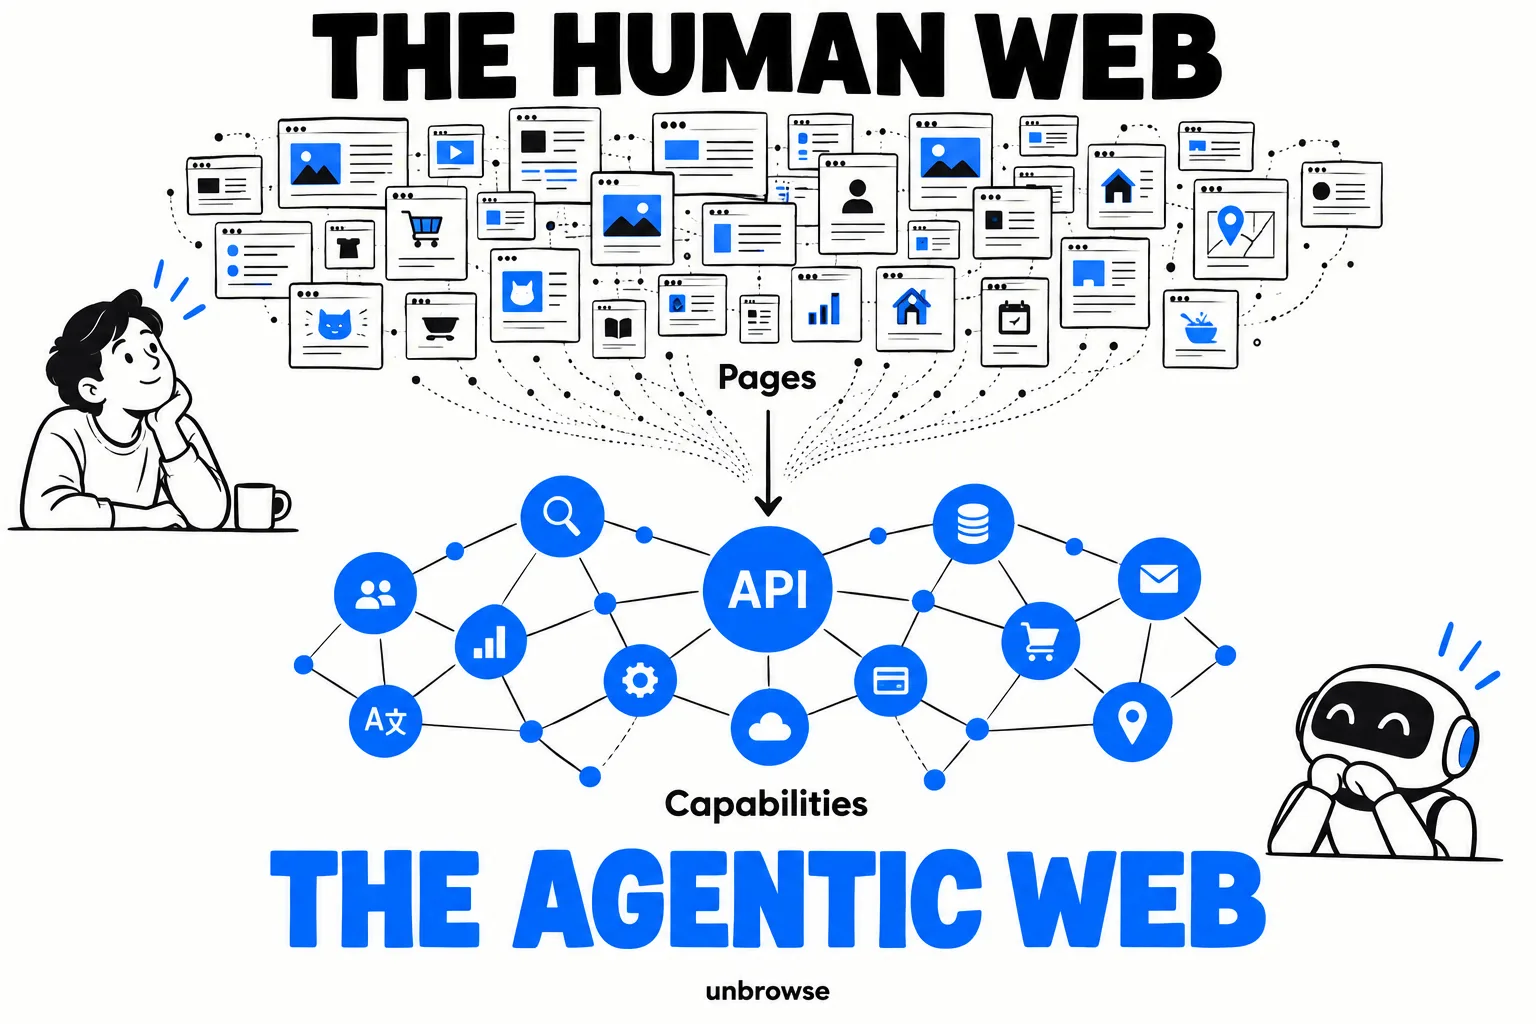
Search indexed what the web knows.
Unbrowse indexes what the web can do.
The agentic web won’t arrive when the last company publishes its MCP server.
It won’t wait for every API roadmap.
It won’t wait for every partnership.
It won’t wait for every website to decide it’s ready.
The capabilities already exist.
The interfaces already exist.
The agents are already arriving.
Sites don’t need to integrate with agents.
Agents can integrate with sites.
The agentic web will not wait.
A note on reuse: the invoice route is illustrative. Learned routes still need verification and maintenance; some operations remain browser-dependent. Reusable route knowledge must exclude credentials and private data. Each user’s access remains their own. This is the direction we’re building toward, not a claim that every website or operation is supported today.